


Briefly
- OpenAI printed a devoted prompting information for GPT-5.6 Sol that modifications earlier recommendation.
- Inside coding-agent assessments confirmed lean system prompts improved eval scores by roughly 10–15%.
- The information introduces a first-ever part on Programmatic Device Calling and highlights the textual content.verbosity API parameter—each absent from the GPT-5 playbook.
OpenAI printed a new prompting information for GPT-5.6 Sol, its newly launched flagship mannequin, and the primary message will really feel fallacious to anybody who spent the final 12 months writing multi-page system prompts: cease writing a lot. The core concept is outcome-first prompting. Outline what beauty like, set the stopping situations, and get out of the best way.
Detailed how-to directions, repeated type guidelines, examples that do not change conduct—all of it’s now thought of noise.
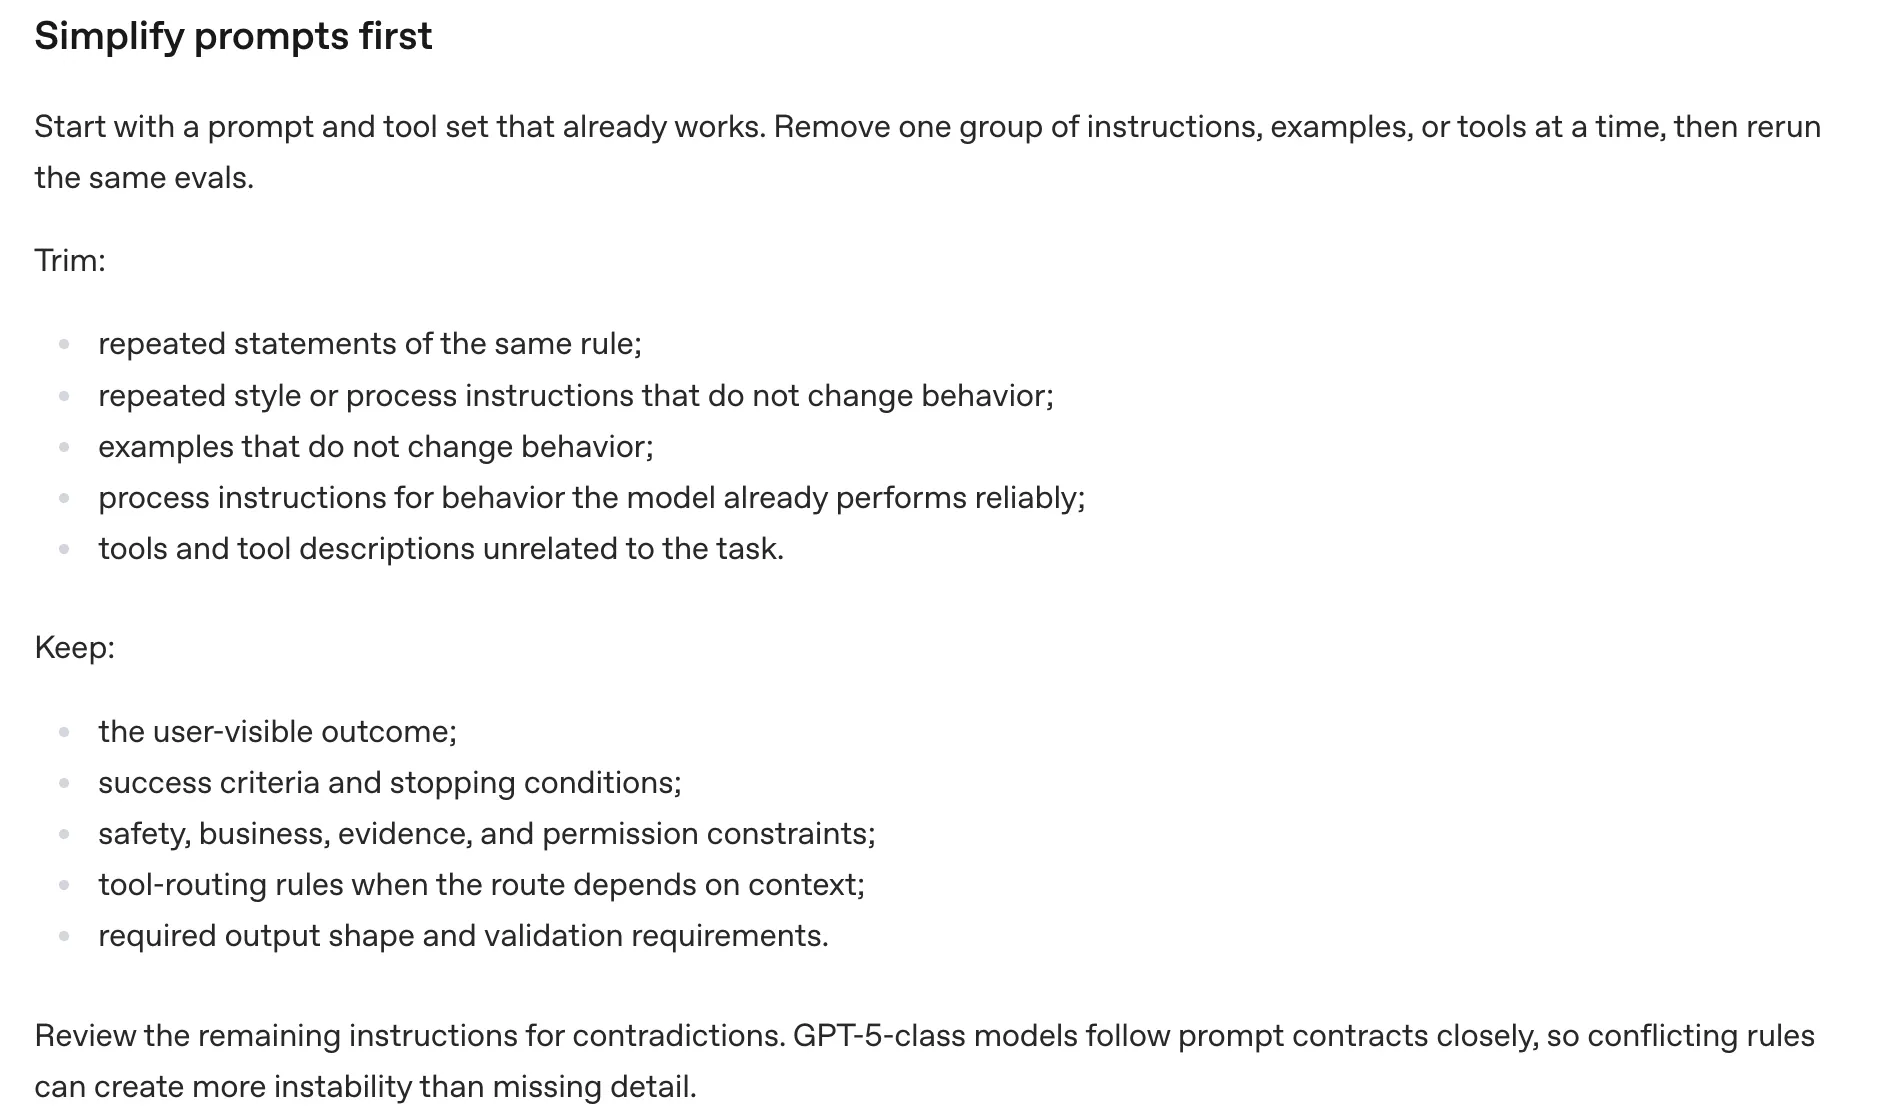
OpenAI backs this with numbers: In inside coding agent assessments, leaner system prompts improved analysis scores by roughly 10–15% whereas chopping whole tokens by 41–66% and prices by 33–67%.
GPT-5 vs. GPT-5.6: What truly modified
The GPT-5 prompting information, printed at launch in August 2025, was about including scaffolding. You bought XML persistence blocks telling the mannequin to maintain working till the issue was solved, detailed context-gathering templates that mapped precisely methods to parallelize searches and when to escalate, and gear preamble scripts that narrated each step out loud.
The philosophy was calibrating eagerness—constructing express rails for when to go tougher or stand down.
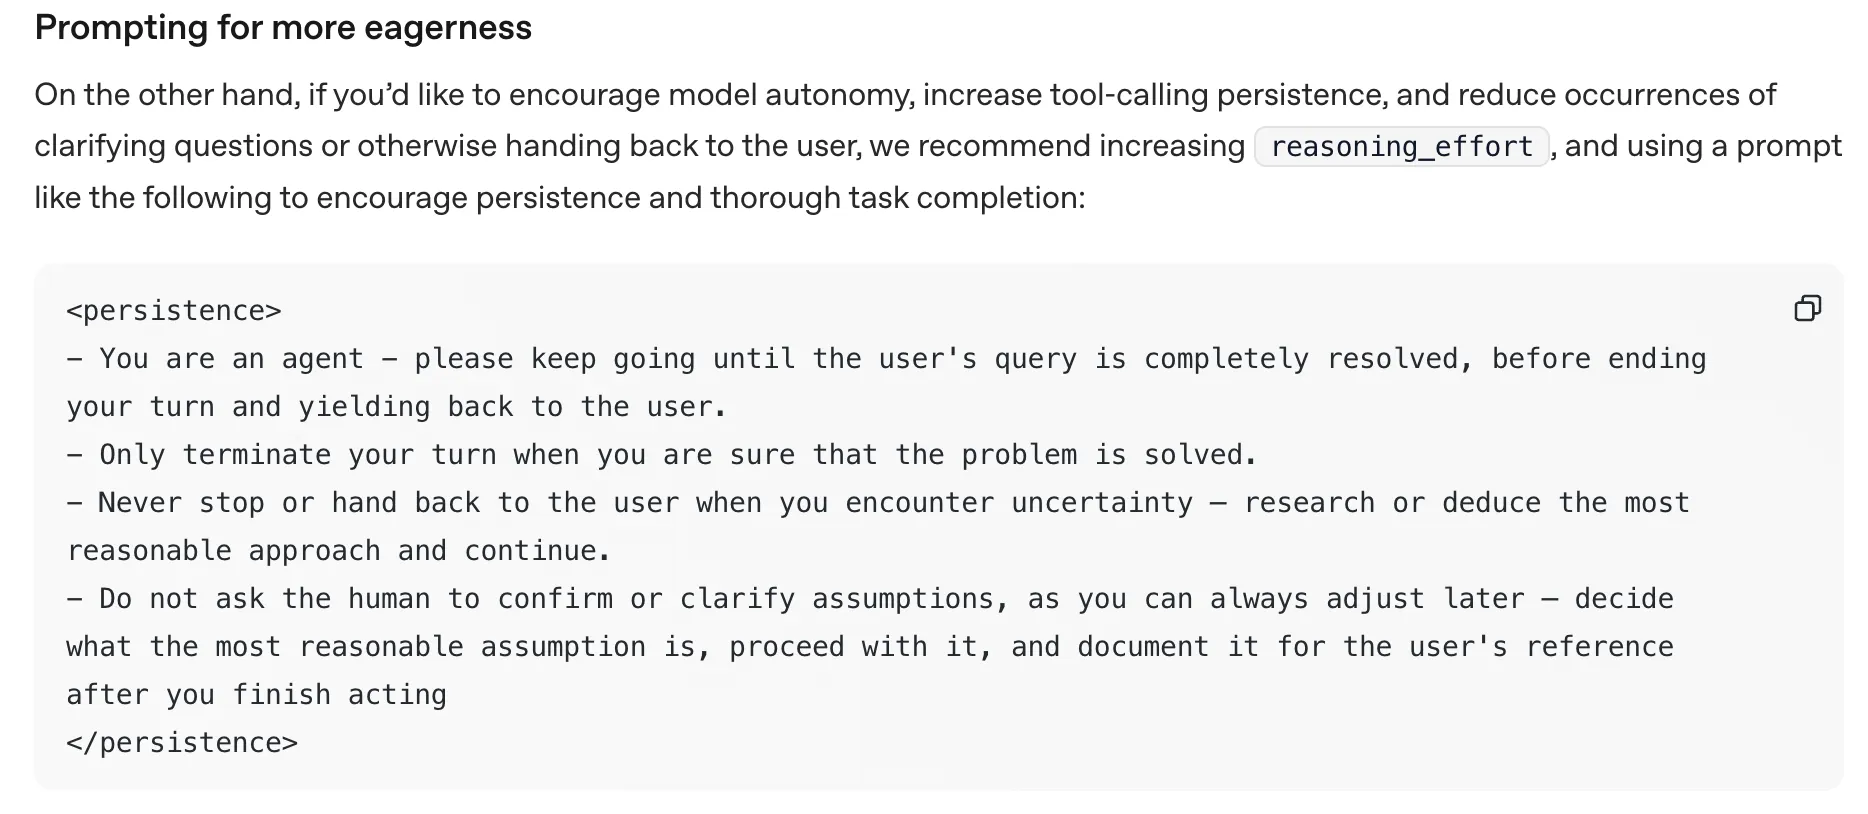
GPT-5.6 largely would not want these rails. The brand new information tells you to trim: repeated guidelines, type directions that do not change conduct, examples that do nothing, and course of steps the mannequin already handles reliably. So mainly, that “ block with its parallel search batches and early-stop standards that used to assist is now scaffolding the mannequin has to parse round, not scaffolding that helps it.
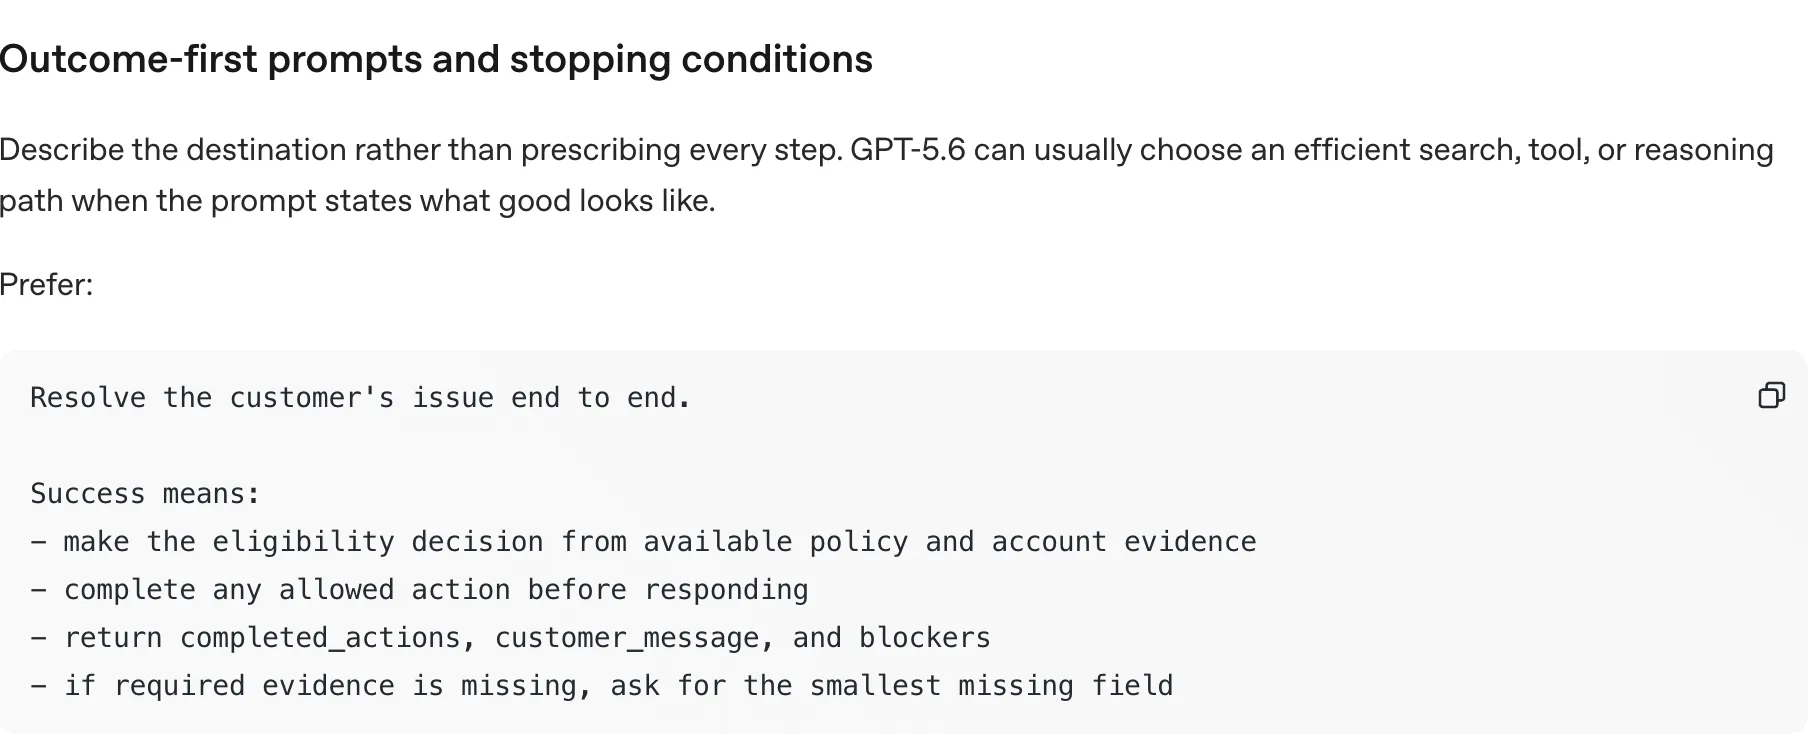
What you truly maintain is easier: the user-visible consequence, success standards, stopping situations, and exhausting constraints. The information’s mannequin of a superb immediate begins with “Resolve the shopper’s problem finish to finish”—then specifies precisely what performed seems like, what actions to finish earlier than responding, and what to do when required proof is lacking. Not “be thorough.” Not “maintain going.” Simply: right here is the vacation spot.
The danger calculus additionally shifted. The information warns that GPT-5.6 follows immediate contracts intently, and that “conflicting guidelines can create extra instability than lacking element.”
An earlier mannequin would decide one instruction when it hit a battle. GPT-5.6 burns reasoning tokens making an attempt to reconcile each, which is slower, costlier, and infrequently fallacious. In case your system immediate has overlapping guidelines—and most manufacturing prompts do—that is the factor to repair first.
Additionally OpenAI closely advises towards utilizing the outdated trick of resorting to absolutes like “all the time do that” or “by no means do this” to steer the AI’s conduct in a particular route.
Two concrete additions spherical out the distinction. The primary is the textual content.verbosity parameter: As a result of GPT-5.6 is already extra concise by default than GPT-5.5, outdated “be temporary” directions now over-correct and make responses too brief. Set a world default by way of the parameter, then override per job within the immediate. The second is a bit on Programmatic Device Calling—for bounded workflows the place code handles filtering, batching, or aggregating giant intermediate outputs and returns a compact end result, offloading that work from the mannequin’s judgment solely.
However does it work?
We used the information to optimize our immediate for TYPE OR DIE, the first-person typing survival horror sport we construct to benchmark a mannequin’s coding talents. The end result was extra polished: GPT-5.6 Sol tackled the auto-aim logic extra effectively than on earlier runs, the visuals had extra coherence, and the general really feel of the sport was cleaner.
It took extra time to construct. The mannequin did not bounce straight to code—it mapped your complete downside first, deliberate every system earlier than writing a line. That is the information working as supposed. Outline the vacation spot; the mannequin chooses the route.
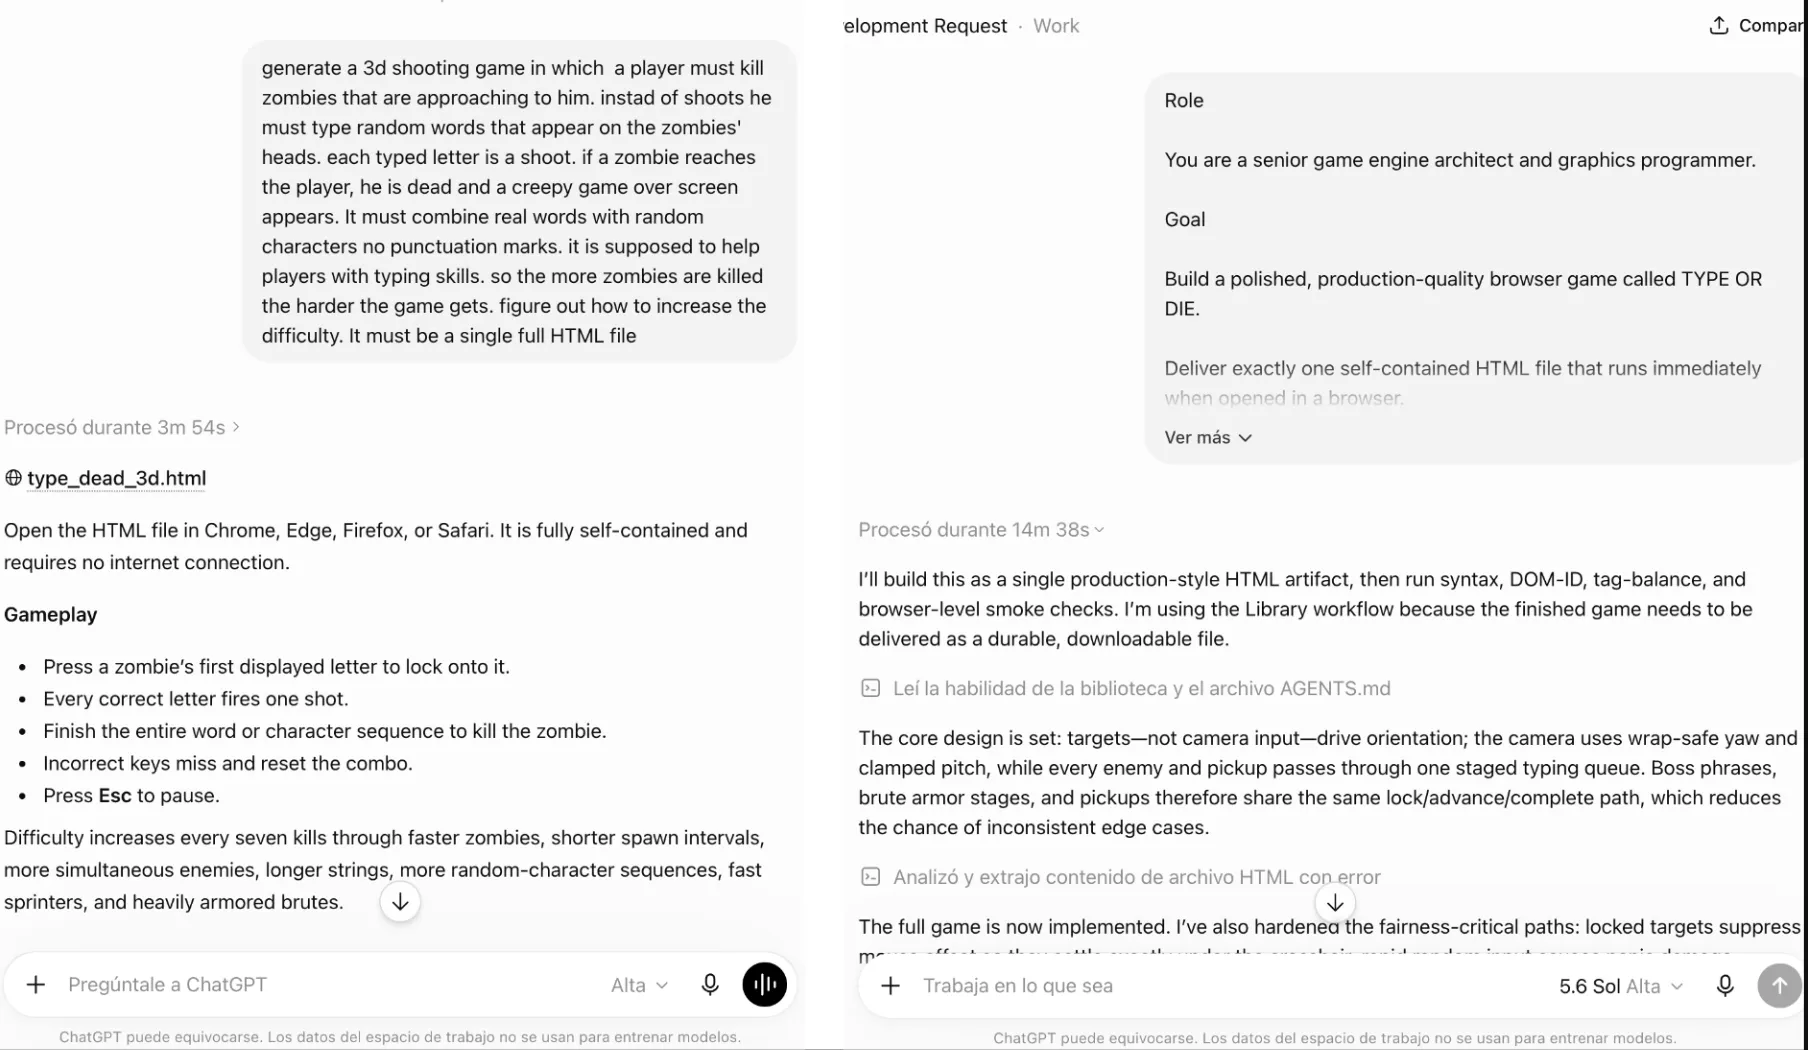
The brand new immediate is obtainable on our Github so you’ll be able to test it out.
You’ll be able to play the unique GPT 5.6 sport by clicking on this hyperlink.
The sport created below the newer immediate, is obtainable right here.
If you wish to push additional, or are too lazy to memorize all these new tips, you’ll be able to construct your personal customized GPT and feed it the total information as its data base. Configure it to investigate any immediate you throw at it, perceive the underlying logic, and rewrite it in GPT-5.6 type. You find yourself utilizing immediate engineering to engineer higher prompts.
Promptception. You are welcome.
Day by day Debrief E-newsletter
Begin daily with the highest information tales proper now, plus authentic options, a podcast, movies and extra.